
What separates a great AI image generator from one that just looks good in a demo? The answer rarely shows up in a five-image gallery on a pricing page. It shows up when you type a long, fussy prompt and the tool ignores half of it, or when you need a poster with legible text and get alphabet soup instead. Picking the right tool means comparing a specific set of features, and knowing which ones affect your actual work.
This guide walks through the features worth checking, the traps that catch new buyers, and what tends to hold up in day-to-day use. It stays balanced on purpose: no tool wins every category, and the “best” choice depends on whether you need commercial safety, speed, control, or privacy.
Start With the Model Type, Because It Shapes Everything
Most leading image generators are diffusion models, which learn by reversing a noising process. The original denoising diffusion work laid the foundation, and latent diffusion made these models fast and practical enough for everyday use. Newer systems, including OpenAI’s GPT-4o image generation announced in March 2025 and Google’s Gemini image models, lean on autoregressive or hybrid approaches.
Why should a buyer care? Because the architecture quietly influences three things you will notice immediately:
- Prompt adherence: how faithfully the tool follows long, detailed instructions
- Text rendering: whether words inside the image come out legible
- Speed and iteration style: whether you get a batch in seconds or a slower, more deliberate edit flow
Vendors rarely disclose full architecture details, so treat this as a starting lens rather than a spec sheet. If you want the mechanics in plain language before comparing products, a primer on how AI image generation works is a sensible first stop. (Compare ai presentation tools before you subscribe)
Prompt Adherence: The Feature Nobody Advertises
This is the single most useful comparison axis, and almost no marketing page mentions it. Prompt adherence means the tool does what you asked, including the boring details: the number of objects, their positions, the color of the jacket, the fact that the sign says “OPEN” and not “OPNE.”
OpenAI reported that DALL·E 3 was built with a captioner to improve prompt fidelity and published its evaluation methodology alongside the release. That matters because it signals a shift: better captions during training tend to produce better instruction following.
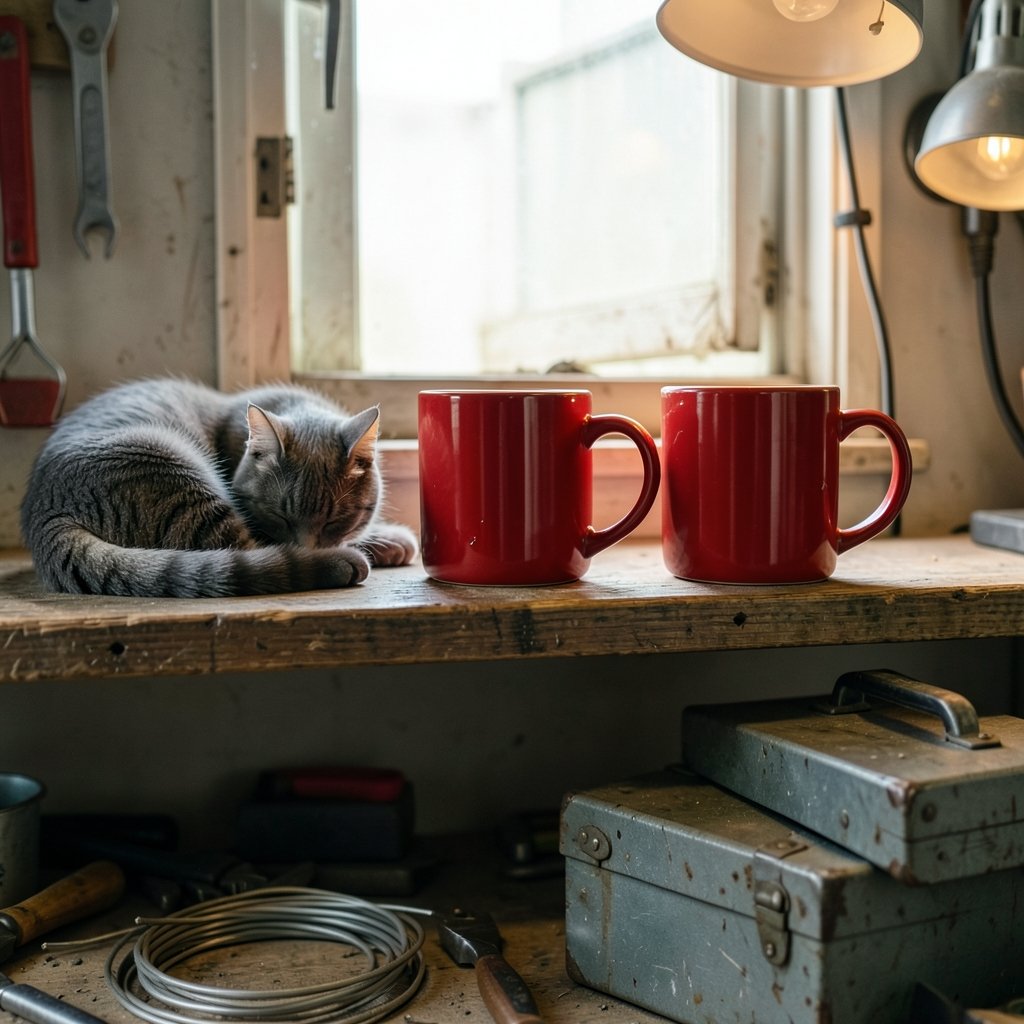
In practice, test adherence with a deliberately awkward prompt. Ask for three red mugs on a wooden shelf, one slightly chipped, a window behind them, and a cat sleeping on the left. Count what you actually get. A tool that nails seven of eight details is easier to work with than one that produces prettier images but drops the specifics.
Compositional benchmarks such as GenEval give a structured way to compare this, though rankings go stale quickly as models update.
Text Rendering Inside Images
Historically the weak spot of AI generators, in-image text has improved sharply. DALL·E 3 arrived in October 2023 with noticeably better text, and tools like Ideogram, GPT-4o, and Imagen 3 pushed further. If your work involves posters, UI mockups, packaging concepts, or social graphics, this feature alone can decide your choice.
A practical test: request a short sign, a product label, and a two-line caption in one image. Then check spelling, kerning, and whether the text sits at a believable angle. Many tools handle a single word well and fall apart at a sentence.
Editing, Inpainting, and Reference Images
Generation is only half the job. Compare these editing capabilities carefully, because they determine how much rework you avoid:
| Feature | What it does | Why it matters |
|---|---|---|
| Inpainting | Redraws a selected region | Fix a hand, swap a background, remove an object |
| Outpainting | Extends the canvas beyond the original frame | Turn a square into a banner or widescreen shot |
| Reference-image conditioning | Uses an uploaded image to guide style or content | Keep a character or product consistent across images |
| Conversational editing | Change an image by describing the change | Faster iteration without re-prompting from scratch |
Inpainting research, including the RePaint method, shows why quality varies: the model must blend new pixels with existing context convincingly. In practice, check whether edges look natural, whether lighting stays consistent, and whether the tool preserves what you did not ask it to touch.
Resolution, Aspect Ratio, and Speed
These are unglamorous but decisive. Compare native output resolution, supported aspect ratios, batch generation, and latency. A tool that only outputs squares will annoy anyone building banners or vertical social assets.
Because these specs change with every release, treat them as “check the current docs” items rather than fixed facts. A quick hands-on trial beats any comparison table, especially since free tiers often cap resolution and batch size.
Licensing, Commercial Use, and Training Data
This is where enthusiasm meets paperwork. Tools differ on whether outputs are cleared for commercial use and on where their training data came from. Adobe markets Firefly as trained on licensed and Adobe Stock content, while Stability AI’s licensing terms have shifted over time.
Two habits save grief:
- Read the vendor’s current terms directly, not a blog summary from last year.
- Check whether your specific use case, such as merchandise or client work, is covered.
Terms change frequently. A tool that was safe for commercial work in one quarter may carry new restrictions in the next.
Provenance and Compliance Features
A feature buyers increasingly ask about: does the tool attach content credentials? The Coalition for Content Provenance and Authenticity publishes a technical standard for cryptographically signed metadata, and several image tools embed it. If your workflow involves publishing, provenance metadata helps document how an image was made.
Regulation is pushing this forward. The EU AI Act, in force since 1 August 2024, requires providers of generative systems to mark AI-generated content in machine-readable form and to disclose deepfakes. If you serve EU audiences, compliance features belong on your comparison list, not in the fine print.
Open Weights vs. Closed APIs
A structural choice with real consequences:
- Open-weight models such as the Stable Diffusion family allow local, self-hosted use and fine-tuning. Good for privacy, customization, and predictable costs.
- Closed APIs like DALL·E, Midjourney, and Firefly offer managed quality, safety filters, and zero setup.
If your images contain sensitive material, running a model locally can be the deciding factor. If you want polish with minimal effort, a closed service usually wins. Many teams end up using both.
Practical Tips and Common Mistakes
A few things that actually work, gathered from how these tools behave in real projects:
- Test with your own prompts, not the gallery. Demo images are curated. Your prompt is the real benchmark.
- Compare before you commit. Subscription stacks add up fast, so compare AI image generation tools side by side and shortlist two or three before paying.
- Check the editing loop as well as generation. Most wasted time happens after the first image appears.
- Watch for benchmark tunnel vision. Human-preference and automated scores are useful, but vendor-reported quality claims are not independent, and rankings age quickly.
- Read licensing terms at sign-up, then again before publishing. This is the most common expensive mistake.
Teams building a broader toolkit often run the same disciplined comparison across categories, whether that means checking presentation tools or board tools before choosing one.
How to Run a Two-Hour Comparison
A structured trial beats weeks of hesitation:
- Write five prompts that reflect your real work, including one with text and one with strict layout instructions.
- Generate the same five prompts in each candidate tool.
- Score each output on adherence, text legibility, and how much editing it needs.
- Test one edit task per tool: remove an object, extend the canvas, keep a character consistent.
- Check resolution, aspect ratios, and batch limits against your actual deliverables.
- Read the licensing and provenance terms.
- Pick one primary tool and one backup.
Two hours of this tells you more than any feature list.
Conclusion
The features that matter most in AI image generation tools are rarely the ones featured in launch videos. Prompt adherence, in-image text quality, editing depth, resolution and speed, licensing clarity, provenance metadata, and the open-versus-closed tradeoff decide whether a tool fits your work. Test with your own prompts, read the terms yourself, and remember that benchmarks and model versions move fast. Choose the tool that survives your real workflow, not the one with the prettiest demo.
Frequently Asked Questions
What is the most important feature to compare in AI image generation tools?
Prompt adherence. A tool that follows long, detailed instructions saves more time than one with marginally prettier output. Test it with a prompt containing specific counts, positions, and colors, then count how many details survived.
How do I test whether a tool renders text well inside images?
Ask for one image containing a short sign, a product label, and a two-line caption. Check spelling, spacing, and whether the text sits at a believable angle. Many tools handle a single word but struggle with sentences.
Do AI image tools allow commercial use of their outputs?
It depends on the tool and changes over time. Some services clear outputs for commercial use, while others restrict certain cases. Read the vendor’s current terms directly rather than relying on summaries, and recheck before publishing client work.
What are content credentials, and why do they matter?
Content credentials are cryptographically signed metadata, standardized by the Coalition for Content Provenance and Authenticity, that record how an image was made. They help document AI involvement, and the EU AI Act requires machine-readable marking of AI-generated content.
Should I choose an open-weight model or a closed API?
Choose open weights if you need local hosting, privacy, or fine-tuning. Choose a closed API if you want managed quality and minimal setup. Many teams use both: closed tools for speed, open models for sensitive or customized work. (Trello alternatives beginners compare board tools choose one)
Why do benchmark rankings for image generators go stale so quickly?
Models update frequently, and many quality claims come from vendors rather than independent testers. A benchmark result reflects a specific version at a specific time. Treat scores as a starting point and verify with your own prompts.
Finally, consider the support ecosystem around each tool. Documentation quality, community forums, API reliability, and the pace of updates all affect day-to-day usability. A model with slightly weaker output but responsive support and clear changelogs may serve a production team better than a flashier competitor that changes behavior without warning. Version pinning matters too: if an update alters output style, workflows built on the previous version can break overnight. Check whether the vendor offers stable model versions or deprecation notices.
Also weigh integration fit. Does the tool connect to your existing design software, asset management, or automation pipeline? An API with predictable rate limits and clear pricing often matters more than a marginal gain in image quality. For teams producing at volume, cost per image and batch throughput can outweigh individual output differences.
None of these factors is decisive alone. The right choice emerges from how they combine against your actual constraints: the prompts you run, the text you need rendered, the edits you perform most, the terms you must satisfy, and the infrastructure you already have. Run the two-hour comparison, revisit it when models update, and keep your scoring notes. A repeatable evaluation process outlasts any single tool, and it turns a crowded, fast-moving market into a manageable shortlist you can trust.



