Imagine several hospitals improving one AI model while each keeps its patient files in its own system. That approach lets organizations learn from patterns across separate datasets without gathering every record in one place. It can help when sensitive data must stay under local control, or when moving records creates legal or technical barriers.
A model update is a change to a model’s parameters, such as its weights or gradients, produced during training. Clients share those updates rather than pooling raw records. Keeping data local reduces some barriers to collaboration, but it does not guarantee complete privacy.
The key distinction is simple: the data stays put, while learning is shared. You will see how that exchange works, where it can help, and what limits you should keep in mind before using sensitive data.
Key Takeaways
- Clients train a shared model using local data.
- Clients usually send model updates, not raw records.
- A central server coordinates the work.
- Local data storage reduces some privacy risks, but cannot remove them all.
- Small simulations can help you learn before a real deployment.
What Is Federated Learning in AI?
In centralized machine learning, organizations usually gather training records in one location, but federated learning sends a model to the locations that already hold them. The key difference is where training data stays. Clients keep raw data local while sharing model updates.
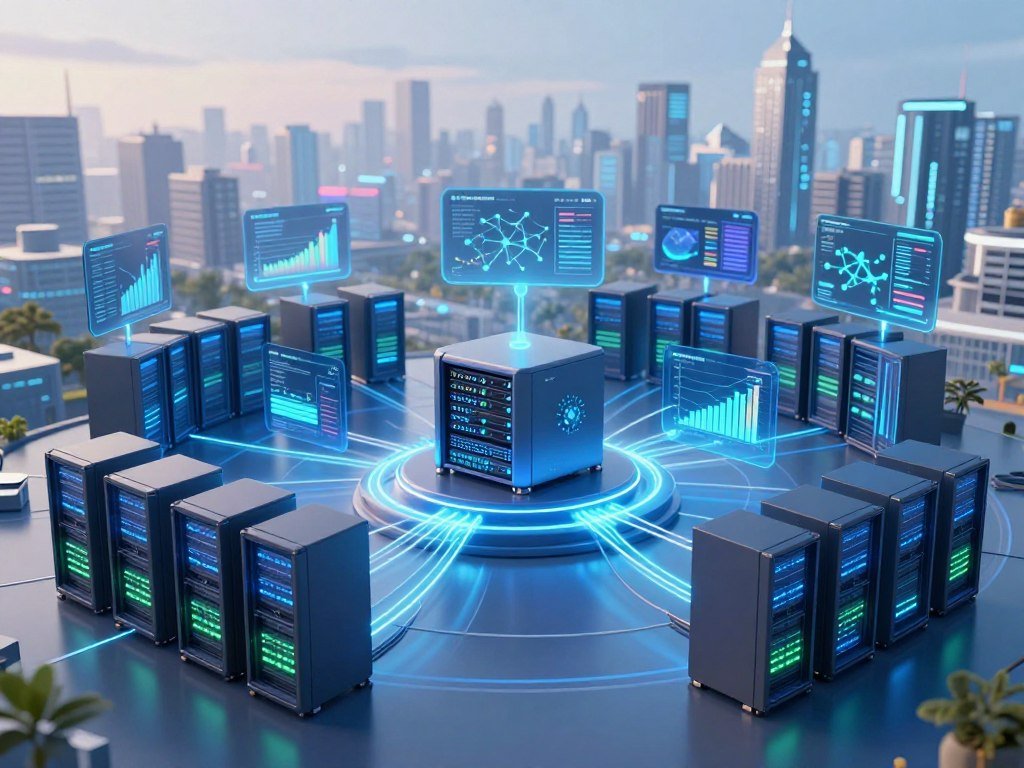
In a centralized setup, a company or research group collects records before training. That can require moving sensitive data across systems, organizations, or borders. In federated learning, a central server sends model instructions to participating clients, such as hospitals, banks, or devices.
Federated learning coordinates training without requiring the central server to collect clients’ raw data.
Each client trains the model with its own local data. It then sends model updates to the central server, which coordinates the shared work. The server does not need to hold the training records themselves.
Bringing a model to the data
This setup is often described as bringing the model to the data. The server distributes a model, and clients train it where their records already live. The clients might run different computer systems, but they need a way to use the shared model and return updates.
That differs from running a model locally just to answer a question. Local AI can process a user’s input on one device, while federated learning trains a shared model across clients. A beginner can learn more about AI models and machine learning before exploring the training process.
Why local records matter
Federated learning was introduced in healthcare in 2018 as a decentralized alternative for collaboration across institutions without sharing patient data. Healthcare collaboration from 2018 reflects the need to learn across clinical settings while keeping records with each organization.
Local storage can also help when transferring records is expensive, slow, or restricted. Each client still needs permission to train its model and share updates. The central server coordinates that work, while clients control their own records.
Keeping records local can make collaboration possible when transferring them is difficult or restricted.
A 2024 review describes how federated learning combines local training with shared model updates. Its overview of strategies and applications also covers tools and security concerns.
How Does Federated Learning Train a Shared Model?
A typical training round starts when the central server sends the current global model to a selected group of clients. The round repeats until the model reaches a chosen stopping point. Each client trains locally, then shares model updates for aggregation.
The global model is the combined trained model that clients help improve. Local training changes its parameters using examples held by each client. If you are new to model training, this step-by-step AI training guide explains how examples adjust model weights.
The server distributes a starting model
A round has five main steps:
- Initialize the global model with starting model parameters.
- Select clients and distribute the current global model to them.
- Train locally, using each client’s own records and computing resources.
- Send model updates, such as changed parameters or gradients, to the central server.
- Aggregate the updates, then send the updated global model back to clients.
The first model can begin with random parameters or an existing model. The central server then chooses which clients will take part in that round. A system may select clients based on availability, computing capacity, or its own training rules.
Clients train locally and return updates
During local training, each client uses its own records to adjust the model. A model update can contain changed parameters or gradients, which describe how parameters should change. Training changes a model; inference uses a trained model to respond to new input without updating its parameters.
Clients send their updates to the central server after local work ends. The server combines them into a revised global model. A common method, federated averaging, or FedAvg, averages client updates, but averaging is not required for every system.
In FedAvg, the server may account for how many training examples each client used. The method helps combine contributions from clients with different amounts of local data. The server then redistributes the combined model, and clients can train it again.
Researchers often repeat rounds because one exchange may not capture enough learning from all participants. The model can change as it receives updates from new or returning clients. Training ends when the system meets its chosen goal, or when the available time or resources run out.
A system can also set limits on how much work each client completes in a round. More local work may reduce the number of exchanges, but can change how updates affect the shared model. These choices are part of the training design, not a fixed rule for every project.
A research paper on communication-efficient learning from decentralized data describes iterative model averaging across devices. Its experiments also examine how training works with data distributed across clients.
If a client disconnects, the round may need to wait for another participant or proceed with the clients that remain, depending on the system’s rules.
What Are the Main Types of Federated Learning?
The type depends on whether participants share the same people, the same data fields, or neither. Two labels describe dataset relationships, while two others describe who takes part. Check both dimensions to understand how a project is organized.
A dataset contains examples, also called samples, and the features recorded for each example. A sample might represent one patient or one customer. Features might include age, diagnosis, account activity, or a scan result.
Data can overlap by samples or features
Horizontal federated learning uses the same feature space but different data instances. For example, clinics may track similar medical fields for distinct patients. Each clinic contributes its own samples while the types of information remain alike.
Vertical federated learning uses shared data instances but different features. A bank and retailer might have information about some of the same customers, but each holds different details. They can work together only when they can match those shared samples in an approved way.
Federated transfer learning can apply when participants have different features and different samples. It uses knowledge learned in one setting to help another, even when their datasets do not line up neatly. Its design can be more complex because there is less overlap to work with.
Participants can be devices or organizations
Cross-device systems involve many separate devices, such as smartphones or Internet of Things devices. Cross-silo systems involve a smaller set of organizations, such as hospitals or banks. Those clients may each hold large datasets and have their own rules for taking part.
Horizontal and vertical describe how datasets relate. Cross-device and cross-silo describe the participant setting. A project can therefore be both horizontal and cross-silo, or use another combination.
| Type | Data relationship | Typical participants | Example |
|---|---|---|---|
| Horizontal | Same features, different samples | Organizations | Clinics with distinct patients |
| Vertical | Same samples, different features | Organizations | Bank and retailer with complementary customer information |
| Cross-device | Local data on many separate devices | Phones or IoT devices | Personalized recommendations |
| Cross-silo | Data held by a limited number of institutions | Hospitals or banks | Collaborative research or fraud detection |
A project’s labels can show why its clients are working together and what kinds of data they hold. A phone network may have thousands of clients with small local datasets. A hospital project may have fewer clients, each with more records and distinct systems.
Edge AI usually runs a model near the device that collects data, while federated learning coordinates training across clients. This guide to edge AI and local processing explains that difference in more detail.
Check both the dataset relationship and the participant setting before comparing two federated-learning projects.
Does Federated Learning Keep Data Private?
Keeping patient files on hospital servers reduces exposure from transferring or pooling those records, but it does not make every part of training private by default. The main limit is that clients still share information about training. Model updates can expose details or be manipulated.
Some attacks can use gradients or parameters to infer details about training data. An attacker might try to reconstruct parts of an example from the updates a client sends. The risk depends on the system, the information in the updates, and who can access them.
Privacy tools add layers of protection
Teams can add safeguards to limit what others learn from model updates. Three methods used in healthcare federated learning include:
- Differential privacy adds carefully calibrated noise to shared information.
- Secure aggregation combines updates while limiting access to individual contributions.
- Confidential computing protects selected computations in isolated environments.
These tools work in different ways and have different trade-offs. Noise can affect model quality, while secure aggregation changes how the server receives updates. Confidential computing protects selected work inside a protected environment, but does not cover every part of a system.
Healthcare teams have used differential privacy, secure aggregation, and confidential computing to help safeguard privacy. These methods still need careful design and testing. They are not automatic guarantees, and they do not by themselves meet every legal or organizational rule.
Shared updates still create risk
Model updates can be reverse-engineered to infer information about the records used during training. A client could also send malicious updates designed to damage the shared model. This kind of manipulation is called a model-poisoning attack.
A 2025 experimental study found that none of its tested attack methods effectively breached private client data in the realistic settings it examined. The study tested state-of-the-art privacy attacks, including settings without defense strategies. That result describes those tests, not every system or future attack.
The gap between a test and a live system matters. Real systems may use different models, records, client behavior, or update rules. A study’s result cannot prove that every client’s updates are safe from inference or misuse.
If you handle sensitive information, review what updates contain and who can access them. You can also read about protecting sensitive data in AI work when planning other data analysis tasks. Local storage is only one part of a wider privacy design.
Choose safeguards based on the information at risk and the way the system shares updates. A privacy review should consider both individual contributions and the combined result. This helps teams spot risks that local storage alone cannot address.
Treat local storage as one privacy layer, then assess what an attacker could learn from updates and the aggregation process.
Where Is Federated Learning Used?
A hospital network can train a shared brain-MRI tumor-segmentation model while each institution keeps its patient records local. That lets the model learn from images across sites without pooling their original records. Federated learning in AI examples include medical-image analysis, keyboard prediction, and cross-bank fraud detection.
Hospitals can collaborate without pooling patient records
Tumor segmentation means marking the parts of an MRI scan that show a tumor. Hospitals may train a model to find those regions in brain scans. Each site keeps its patient information in its own system and shares model updates instead.
For example, hospitals may have scans from different machines or patient groups. A shared model can learn from a wider range of cases than one site’s records alone. The result still needs testing with data that reflects the people and scans it will face.
A healthcare review found that medical imaging was the most common data type in the studies it examined. Brain MRI work is one example of how teams can test shared training across institutions. A model’s usefulness depends on the task, the available records, and how well it works in practice.
Devices and banks can learn from local activity
Mobile keyboard prediction can learn patterns from how people type without uploading their typing data to a server. A device trains on local activity and shares model updates. The app can use those updates to improve predictions across participating devices.
This can help keep personal typing records on a device, though updates still need suitable safeguards. A phone may also have limited battery, memory, and network access. Those limits shape when it can train and send updates.
Banks could use federated learning for fraud detection across local transaction records. Each bank could train on its own customer activity and send updates without exchanging raw customer data. The shared model could learn patterns that appear across participating banks.
Cross-bank fraud detection would not mean that every bank shares the same customer records. It would mean that each bank contributes to training while keeping its own transactions local. Teams would still need to test whether the model catches fraud without flagging too many valid transactions.
These use cases show why organizations may want shared learning without handing over records. A model trained across more sites may encounter more kinds of examples. That possibility is a reason to test the approach, not a promise of better results.
Before using a model for a real decision, teams should check how it performs for the people and conditions it will serve. For medical images, that includes checking scans from the settings where clinicians plan to use it. For transactions, it includes checking different types of fraud and normal customer activity.
A useful application is one where the shared model can benefit from wider patterns without requiring participants to hand over the records they protect.
What Are the Downsides of Federated Learning?
A shared model can struggle when one hospital has many varied records and another has a smaller, more specialized dataset. The uneven mix can affect how well training works across clients. Data size and diversity both shape model performance.
Healthcare model performance depends in part on the number of training examples. Generalizability, or how well a model works on new cases, depends on the diversity of those examples. A model trained on a narrow group may not work as well for people outside that group.
Data and devices can differ across clients
Four common challenges can make a project harder to run:
- Client data distributions can differ, so local records may not reflect the same patterns.
- Client devices have unequal computing and network capacity.
- Repeated exchanges create communication overhead between clients and the server.
- Participating systems need interoperable infrastructure to work together.
A hospital with a large, varied dataset may affect the global model differently from a small clinic focused on one condition. If one group’s records dominate, the model may learn patterns that fit that group best. Teams need to check results across clients, not only in one combined score.
Devices also differ in speed, storage, battery life, and network access. A phone may be offline when a round starts, while a hospital server may stay connected. A system must account for those differences when choosing clients and scheduling work.
Real-world systems need reliable infrastructure
Communication can take time because clients exchange updates over a network. The cost grows when many clients take part or when updates are large. Training rules can limit some exchanges, but those choices may also affect model quality.
Organizations also need systems that can exchange the right data formats and run compatible software. Healthcare deployment needs scalable infrastructure that works across institutions. Without that foundation, a promising test may be hard to run as part of daily work.
Real-world research remains a smaller part of healthcare federated learning than technical designs and prototypes. A systematic review of 612 articles found that only 5.2% reported real-life applications. The healthcare review also describes technical and deployment limits.
Model quality can also change as local records change over time. A new device, patient group, or business rule may create patterns that earlier training did not include. Clients need a plan to check whether model performance remains useful as their data and systems change.
Before a pilot, check whether the participating data are both large enough for the task and diverse enough to represent the people who will use the model.
Which Federated Learning Frameworks Can Beginners Try?
A beginner can test federated training in a simulation before connecting real devices or institutional data. Two open-source options are Flower and TensorFlow Federated, also called TFF. Both let you study client training without starting with sensitive records.
Flower supports several machine-learning stacks, including PyTorch, TensorFlow, Hugging Face Transformers, scikit-learn, JAX, and XGBoost. It can help beginners test a training design with familiar tools. Flower also has examples that show how a simulation can divide data among clients.
Flower supports several machine-learning stacks
One advanced PyTorch example uses Fashion-MNIST, a dataset of clothing images. It splits the data non-identically across 50 partitions with a Dirichlet partitioner. Non-identical splits give clients different data mixes, which can help reveal how uneven records affect training.
The simulation uses 50 virtual nodes. Its default setup samples 25% of those nodes for training and 50% for evaluation, while ClientApp objects run on CPU by default. Those are settings for that example, not rules that apply to every Flower project.
| Example | Dataset or stack | Configuration or output |
|---|---|---|
| Flower advanced PyTorch example | Fashion-MNIST | 50 Dirichlet-partitioned partitions |
| Flower simulation defaults | 50 virtual nodes | 25% sampled for training, 50% for evaluation, CPU ClientApps |
| TFF documented example | EMNIST | 3 client datasets, weighted FedAvg, SGD at 0.1 for 5 rounds |
Flower’s example also demonstrates stateful clients, checkpoint saving, metric logging, and a learning-rate schedule that decays over time. It can log accuracy and loss to Weights & Biases. The example stores results in a file named results.json.
These features can help you see how a training run changes over time. A checkpoint saves model state so training can resume or be reviewed. Metric logs help you track results, but accuracy and loss alone cannot show whether a model works well for every client.
TensorFlow Federated provides simulation examples
TensorFlow Federated is an open-source framework for machine learning and other computations on decentralized data. It includes tools for simulating federated algorithms. A documented example loads EMNIST simulation data and selects three client datasets for training.
The TFF example builds a weighted FedAvg trainer with stochastic gradient descent, or SGD, set to a learning rate of 0.1. It then runs five training rounds. Those small settings make it easier to study a complete run before using a larger dataset or different model.
Flower and TensorFlow Federated are open-source projects with GitHub repositories. TFF also identifies mobile-keyboard prediction as an application. You can inspect example code to see how clients, training rounds, and results fit together.
A beginner can change one setting, such as the number of clients, then compare the output. Keep other settings the same so the effect is easier to understand. Public sample data also avoids the need to start with records that require special protection.
Start with a simulation that matches your machine-learning stack, then change one setting at a time so you can see its effect.
Conclusion
Federated learning is most useful when collaboration matters but moving raw records is not an acceptable first step. Clients train on local data and share model updates, while a central server coordinates the work. That design can reduce the need to pool records, but updates and system choices still matter.
Privacy safeguards, model testing, and reliable infrastructure all shape whether a project works well. Treat local data storage as one part of the design, not proof that every risk has disappeared. A small simulation can show how clients exchange information before you consider a real deployment.
Try Flower or TensorFlow Federated with public sample data first. Choose a small run, inspect the updates and results, then decide what questions need answers before sensitive data enters the system. Choose a small public-data simulation and inspect what the clients send before planning a real deployment.
FAQ
What is AI Federation?
AI federation broadly describes independent systems working together, while federated learning specifically trains a shared model without pooling raw data. The term “AI federation” can cover different forms of coordination, so it does not always mean model training. In federated learning, clients train locally and share model updates with a central server. The clients keep their original records in their own systems.
Can you give me an example of distributed learning?
Hospitals can train a brain-MRI tumor-segmentation model together while keeping patient records at each institution. Each hospital trains the model with its own scans and shares model updates. A central server combines those updates into a global model. The hospitals can then test the shared model on their own data and review how well it identifies tumor regions.
What is federated learning used for?
Federated learning can support medical-image analysis, mobile-keyboard prediction, and fraud detection across banks. Hospitals can train models on scans without pooling patient files. A keyboard can learn from typing patterns on devices without uploading those records. Banks can compare patterns in transaction data through model updates, rather than exchanging raw customer records. These are use cases, not promises of better results.
What are the downsides of federated learning?
Federated learning can be harder when client datasets are uneven or non-identical, and devices have different computing power. Repeated updates also create network communication overhead. Organizations need compatible, interoperable infrastructure to run the system together. A model may perform unevenly when some clients have small or narrow datasets, so teams should check results across groups before relying on it.
Can federated learning guarantee complete privacy?
No, federated learning cannot guarantee complete privacy. Raw data stays local by design, but model updates may still reveal information about training records. Updates could also be manipulated to harm the shared model. Tools such as differential privacy and secure aggregation can add protection, but each has limits and trade-offs. Teams must assess the full system, not just where the original records live.
Do devices send their raw data to the central server?
No, clients typically send model updates, such as parameters or gradients, instead of raw training records. The central server uses those updates to build or revise the global model. The exact information shared depends on the system’s design. Updates do not equal raw records, but they can still carry clues about the data used for local training.



