
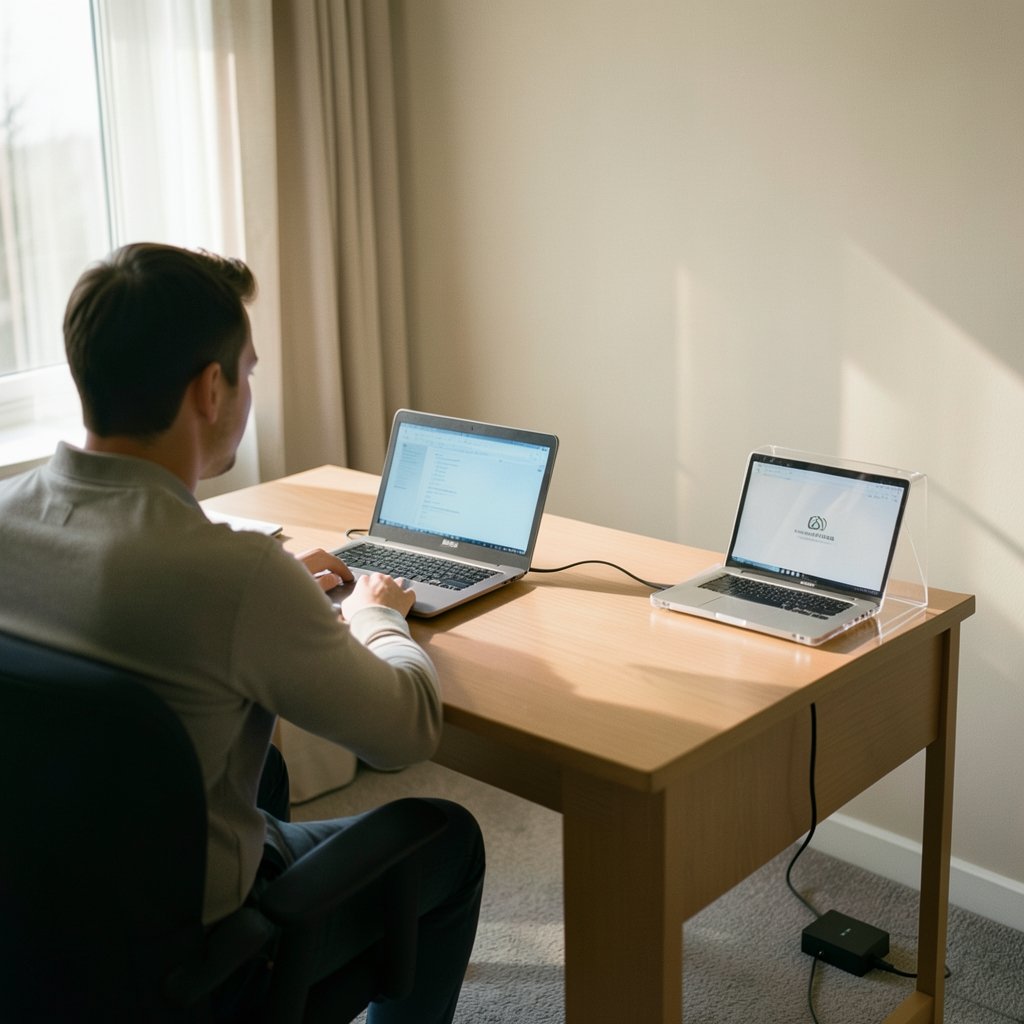
What if the safest place to open a suspicious website was a computer that isn’t yours? That is the basic idea behind browser isolation. Instead of letting a web page run code on your laptop, phone, or work computer, the page runs somewhere else. Only a safe picture of it reaches your screen.
The term confuses many people because it describes several different things. Some isolation happens inside one browser. Some happens in the cloud. Some runs in a locked-down virtual machine. This guide sorts out the differences in plain language, shows where each type fits, and points out the mistakes beginners make when they try to set it up. (Best ukulele for beginners)
What browser isolation actually means
Browser isolation is a security approach that keeps untrusted web content away from the device and network you care about. The page is loaded in a separate environment, called a container or sandbox. What you see is either a stream of pixels or a cleaned-up copy of the page.
The goal is simple: if a malicious page tries to install malware, steal cookies, or reach your internal network, it hits a wall. The wall is the isolated environment.
Security teams treat this as part of a zero trust mindset, where nothing on the web is trusted by default. The U.S. National Institute of Standards and Technology describes isolation techniques in its Zero Trust Architecture guidance, which is a good starting point for anyone who wants the official framing.
The three kinds of browser isolation people mix up
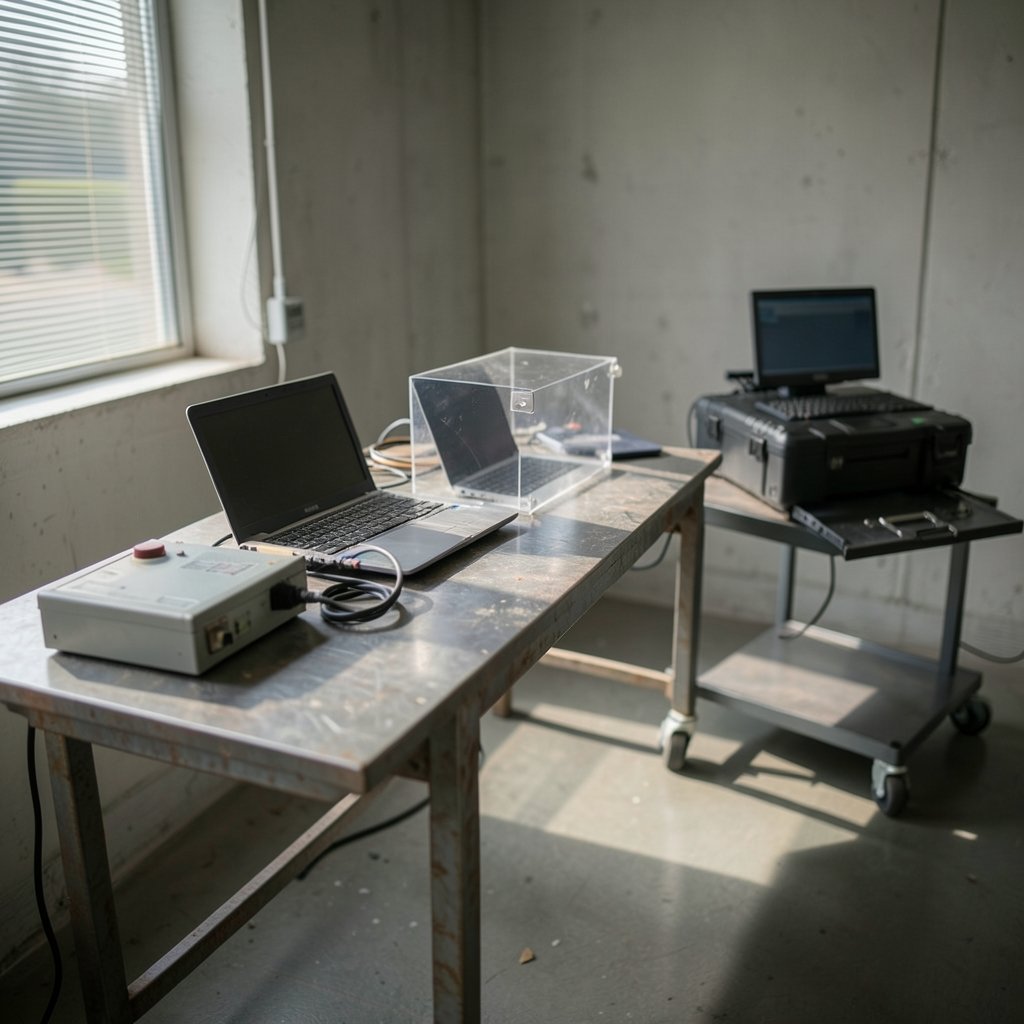
Most beginner confusion comes from one phrase covering three different technologies. They are not the same, and they solve different problems.
| Type | Where it runs | What it protects | Typical user |
|---|---|---|---|
| Remote browser isolation (RBI) | Cloud server or on-site appliance | The whole device and corporate network | Companies protecting staff |
| Browser site isolation | Inside your own browser | One tab from another tab | Everyone using Chrome or Edge |
| Application sandboxing | A virtual machine or container on the device | The device from a risky app or session | IT admins, power users |
Remote browser isolation is the heavyweight option. A remote server loads the page and sends back only the visual result. Site isolation is built into modern browsers and separates websites into different processes so one page cannot read another’s data. Application sandboxing, such as Microsoft’s Application Guard, runs a browsing session inside a disposable virtual machine.
A beginner should know which one they are reading about before comparing products. A vendor selling “browser isolation” may mean any of the three.
How remote browser isolation works step by step
The flow is easier to follow as a sequence than as a diagram.
- A user clicks a link in an email or types a web address.
- The request goes to an isolation server instead of straight to the website.
- The server opens the page in a disposable container.
- The page’s code runs there, not on the user’s device.
- The server sends back pixels, a cleaned-up page, or a rewritten version of the page.
- When the session ends, the container is destroyed and any malware goes with it.
- Policy rules decide what the user can do, such as download a file or copy text.
The delivery method matters. Pixel streaming is the most secure because the browser never touches real code, but it can feel laggy on slow connections. DOM rewriting sends a modified page that looks normal and feels fast, but it relies on the rewriting engine catching every threat. Many products blend both. (Secure Our World)
Why organizations adopt it
The pitch is straightforward. Employees need to browse the open web, and blocking everything is not realistic. Isolation lets people visit unfamiliar sites without exposing the corporate network.
Common reasons teams adopt it:
- Ransomware and phishing defense. A link in a phishing email can be opened safely.
- Protecting unpatched devices. Older machines stay usable for longer.
- Third-party and contractor access. Visitors can reach internal web apps without a full VPN.
- BYOD programs. Personal devices can access work resources with less risk.
- Compliance pressure. Regulated industries need documented controls around web traffic.
The trade-off is real. Isolation adds latency, complicates file downloads, and can break sites that rely on rich JavaScript. A good rollout starts with a pilot group and a clear list of exceptions.
What it does not fix
Beginners often assume isolation solves every web threat. It does not.
Isolation does not stop a user from typing a password into a fake login page. It does not prevent data leaks if someone copies sensitive text into a web form. It does not replace patching, email filtering, or endpoint detection. It also does not help with threats that arrive through other channels, like a malicious USB drive or a poisoned software update.
Think of it as one layer in a stack, not a replacement for the stack. Teams that treat it as a silver bullet usually end up disappointed.
Getting started: practical steps that actually work
If you are evaluating isolation for a small team, the process is less intimidating than it sounds.
- Define the risk you are solving. Phishing clicks, contractor access, and unpatched laptops need different designs.
- Pick the deployment model. Cloud services are faster to start. On-site appliances give more control and keep traffic inside your network.
- Run a pilot with ten to twenty users. Choose people who browse widely, including staff outside IT.
- Set clear policies. Decide which sites are isolated, which are blocked, and which are allowed directly.
- Test file downloads and uploads. This is where most rollouts stumble.
- Measure the experience. Ask pilot users about speed and broken pages before you expand.
- Document exceptions. A short list of sites that must bypass isolation prevents daily support tickets.
For readers who want to go deeper into how automated tools interact with the web, a look at AI browser agents shows how automated browsing raises new questions about what should and should not run inside a sandbox.
Common mistakes beginners make
A few patterns show up again and again.
- Confusing site isolation with remote isolation. Chrome’s site isolation is a browser feature, not a security product. It protects tabs from each other but does nothing about malware reaching the device.
- Isolating everything. Isolating every site slows work and frustrates users. Most programs isolate unknown and uncategorized sites and allow trusted ones directly.
- Ignoring the download path. A user who downloads a file from an isolated session may still open it locally. Policy must cover both downloads and browsing.
- Skipping the pilot. Teams that roll out to everyone at once tend to hit a wall of complaints.
- Forgetting mobile. Staff browse on phones too, and isolation coverage often stops at the desktop.
- No logging. Without records of what was isolated and what was blocked, you cannot tune the system or prove it works.
Another quiet failure is assuming users understand the tool. A five-minute explainer on why some pages look slightly different prevents a lot of confusion. The same principle applies to everyday tech habits: small bits of know-how, like learning how to clear browser cache and cookies, save people from bigger problems later.
How it fits with zero trust and modern security
Zero trust means verifying every request rather than trusting anything inside the network. Isolation fits neatly into that model because it treats every web page as untrusted until proven otherwise.
The practical benefit is granularity. Instead of a blunt allow-or-block decision, a security team can say: this site is fine, this one is isolated, and this one needs approval. That flexibility matters for organizations where blocking the web outright would grind work to a halt.
There is a cost angle too. Isolation can extend the life of older hardware because the heavy lifting happens on a server. For budget-conscious teams, that can offset part of the subscription price.
A quick comparison of deployment options
| Option | Setup effort | Latency | Control | Best for |
|---|---|---|---|---|
| Cloud-hosted RBI | Low | Medium | Medium | Fast rollouts, remote teams |
| On-premises RBI | High | Low | High | Regulated data, strict networks |
| Built-in site isolation | None | Very low | Low | Everyone, as a baseline |
| Local sandbox (VM) | Medium | Low | Medium | Individual high-risk users |
The honest answer for most small organizations is to rely on built-in site isolation as a baseline and add remote isolation only where the risk justifies the cost. Isolation is a tool with a price, and the price includes user patience. (Browser isolation)
Conclusion
Browser isolation is not one product but a family of techniques that keep risky web content away from the things you want to protect. Remote browser isolation moves the page to a server. Site isolation keeps tabs apart inside your browser. Sandboxing traps a session in a disposable machine. Each one solves a different slice of the problem.
For beginners, the key is to name the specific risk first, then pick the technique that matches it. Start small, measure how it feels, and treat isolation as one layer in a wider defense rather than a magic shield. Done that way, it quietly removes a whole category of worry from everyday browsing.
Frequently asked questions
Is browser isolation the same as a VPN?
No. A VPN hides and encrypts your traffic but still lets web code run on your device. Isolation moves the page somewhere else so the code never reaches your machine. They can be used together, but they solve different problems.
Does browser isolation slow down browsing?
It can. Pixel streaming adds noticeable delay on slow connections, while DOM rewriting feels closer to normal browsing. Most users notice only a slight difference on a decent connection, but heavy sites and video calls can suffer.
Can browser isolation stop phishing?
It reduces the damage from malicious links, but it does not stop someone from typing credentials into a convincing fake page. Isolation works best alongside email filtering, multi-factor authentication, and user training.
Do regular home users need remote browser isolation?
Usually not. Built-in site isolation in modern browsers covers the basics for most households. Remote isolation makes more sense for organizations with valuable data, many users, or a large attack surface.
Is browser isolation expensive?
Costs vary widely. Cloud services charge per user per month, while on-premises setups require hardware and staff time. Small teams often start with built-in protections and add remote isolation only for high-risk roles.
What happens to files downloaded in an isolated session?
It depends on policy. Some systems block downloads entirely, some scan files before release, and others let files through with a warning. This is one of the first settings to review during a pilot.
That last question deserves emphasis: download policy is where isolation projects most often succeed or fail quietly. A system that isolates browsing but releases every file unchecked gives attackers a simple bypass. Decide early whether downloads are blocked, scanned, or released with a warning, and test that path during the pilot. Uploads matter too, since staff often paste documents into web forms.
With those pieces in place, the rest is maintenance. Review logs monthly, revisit exceptions as sites change, and retrain users when pages look different. Isolation will not make anyone invincible, but configured with care, it turns the open web from a constant gamble into a managed risk.



